
Solana validator coordination now operates on a 250-millisecond target slot time. A slot is the network’s target interval for a validator to produce a block, so the change gives users more frequent opportunities for transactions to land while giving validators less time to pass production from one leader to the next.
The change became effective at epoch 1037 on Sept. 18, according to the Solana engineering changelog and a Solana Compass report that placed the transition at about 05:06 UTC. One early Sept. 20 sample covering 60 one-minute windows observed about 266ms per produced slot. Epoch 1037 skipped about 0.05% of its scheduled slots.
The narrow observation window supports an encouraging first reading, not a long-term performance trend. The more important test is whether leader handoffs, transaction forwarding, repair and multiple validator clients remain reliable as Solana considers a conditional move to 200ms.
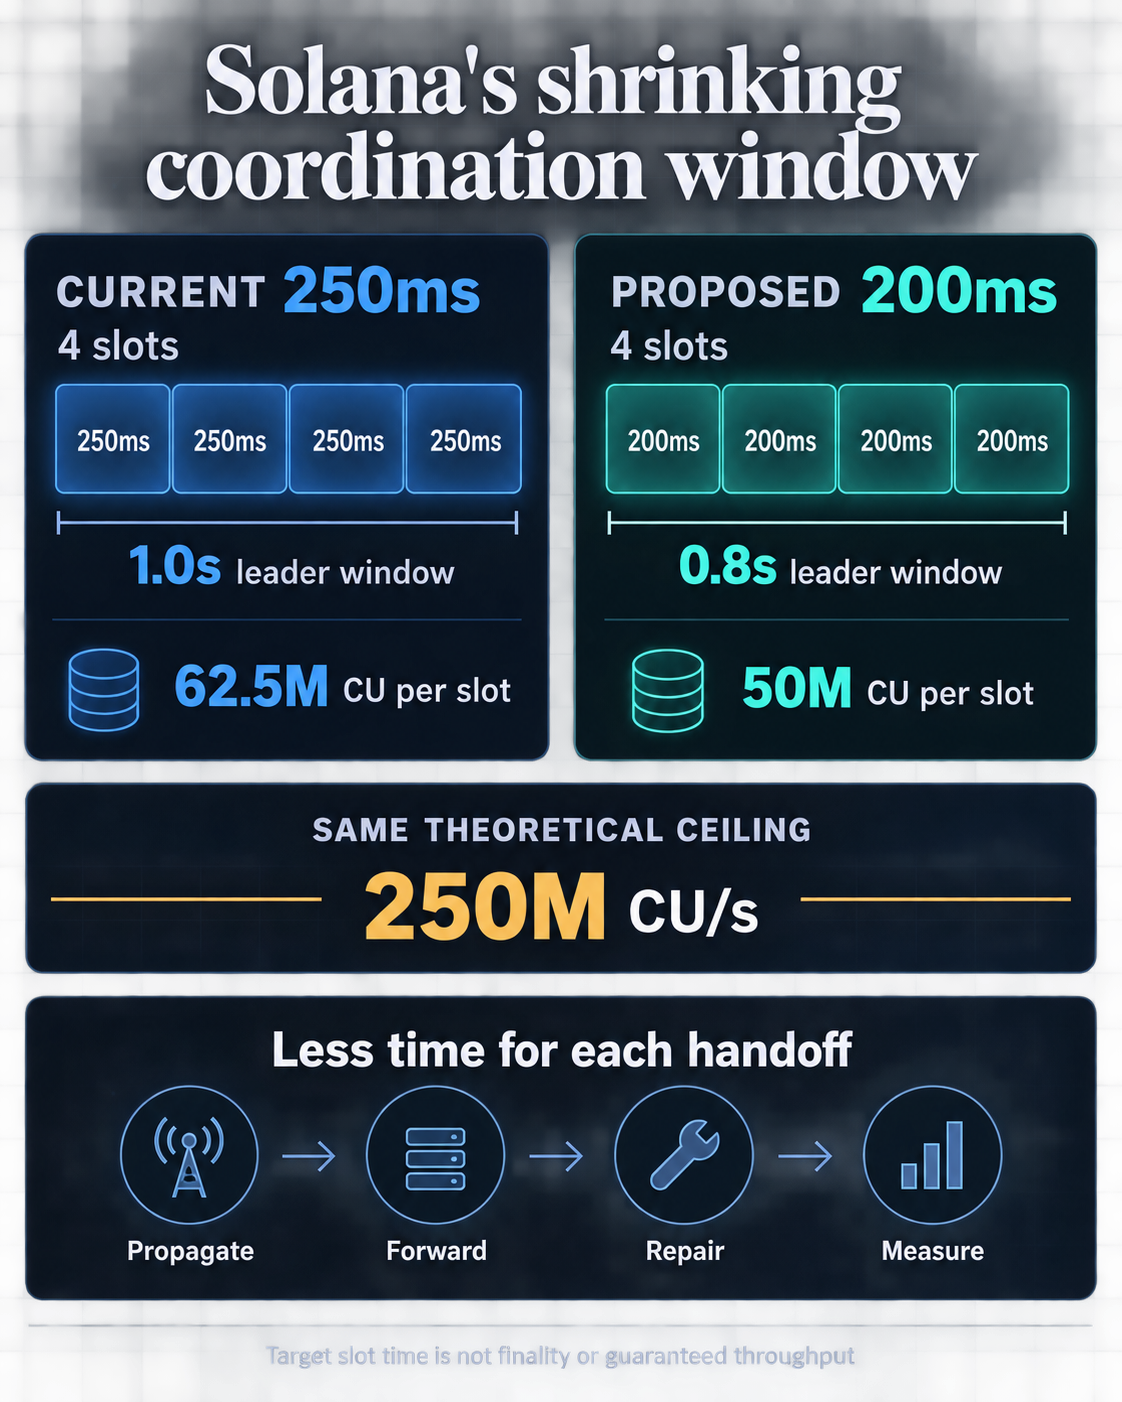
The draft SIMD-0525 design cuts per-slot work limits as slot duration falls. The block budget is 62.5 million compute units at 250ms and would be 50 million at 200ms. Both settings leave the nominal protocol ceiling near 250 million compute units per second.
Shorter slots therefore change cadence and latency more directly than capacity. Blocks arrive more often, but each carries less permitted work. Demand, scheduling and how effectively leaders fill blockspace still determine realized transaction throughput.
The same design keeps a leader’s turn fixed at four slots. That gives each leader a nominal one-second window at 250ms and an 800ms window at 200ms. Users get more frequent chances for inclusion, while validators get less time to receive traffic and begin producing after a handoff.
Geography already consumes part of that margin. A Solana Foundation engineering analysis measured a median first-slot duration penalty of about 28ms when consecutive leaders were less than 500 kilometers apart and 122ms when they were more than 8,000 kilometers apart. The larger figure equals 61% of a 200ms target slot.
The metric compares a leader’s first slot with its later slots and captures more than network latency alone. It nevertheless shows the trade-off: geographic distribution can reduce common-location risk while long-distance handoffs use more of a shrinking production window.
Solana’s Sept. 18 changelog identifies two ways engineers are trying to protect that window. Agave developers are working on pessimistic forwarding to the next leader when a transaction may miss its intended destination. Client teams are also testing block and transaction execution against conformance binaries across implementations and versions.
Recovery has a similar constraint. The draft proposal retains a 250ms repair-defer threshold at its 200ms stage, making that delay longer than one target slot. These are prospective engineering margins rather than evidence of a current failure, but they define the conditions under which lower latency can coexist with reliable execution.
The Aug. 12 routing failure at TeraSwitch happened before the 250ms setting and was not caused by it. It still shows how a shared infrastructure dependency can affect many apparently independent validators at once.
TeraSwitch’s incident report says 12 sites lost reachability and a Miami site was removed for containment. Solana Compass measured 28.83% of network stake as delinquent for about 33 minutes. The Solana Foundation’s account said blocks continued and transactions kept landing.
The network absorbed the failure without a halt, but the event also showed why validator count tells only part of the decentralization story. Independent data dated Sept. 7 put Solana’s stake-based Nakamoto coefficient at 18 and its largest validator near 4% of active stake. At the hosting layer, the same date’s provider report put TeraSwitch at 22.1% of active stake.
The Foundation has separately said TeraSwitch hosted 38% of stake “last year” before its share was reduced below 30%. Those figures lack a common date and method, so the Sept. 7 reading is the cleaner current snapshot rather than one point in a continuous series.
Software creates a third failure domain. A Sept. 20 stake-weighted query grouped roughly 87.4% of stake on 4.x client versions, 7.3% on 0.x and 5.3% on 26.x. Major-version numbers serve only as rough markers for Agave-family, Frankendancer and Firedancer software because they cannot separate every scheduler variant or downstream build.
The three measurements answer different questions. Validator stake shows how many leaders would need to fail or coordinate. Client lineage shows exposure to common implementation faults. Hosting share shows how much stake can disappear behind one provider or routing domain. Faster slots do not create those concentrations, but smaller handoff and repair margins can make correlated disruptions more consequential.
The 200ms feature remained pending for mainnet on Sept. 20, with no firm activation date in Anza’s feature-gate schedule. Solana’s reduced-slot-time page says further reductions depend on acceptable network performance, including skip rates.
One completed epoch with a roughly 0.05% skip rate is a useful baseline. A stronger decision would rely on sustained slot duration, skip, transaction-landing and leader-handoff measurements, broken down where possible by client family and infrastructure provider. That would reveal whether a clean network-wide average hides a weaker cohort or a longer tail.
Alpenglow belongs on a separate timeline. It is a consensus upgrade targeting roughly 150ms finality, whereas slot time governs the cadence of block-production opportunities. Solana’s official pages give different planning windows, from a Q3 target to an October Agave 4.3 window, and neither supplies an exact activation day.
Solana’s first 250ms readings show no immediate skip-rate shock. Reaching 200ms will require the same result across a longer window and under less favorable conditions. The binding test is whether transaction forwarding, leader transitions, repair and different client implementations can keep pace when geographic and provider concentration removes part of the network’s timing margin.
The post Why Solana’s new 250ms speed boost could actually trigger network instability appeared first on CryptoSlate.

Brian Armstrong, CEO of Coinbase exchange, has once again made a bullish long-term projection on Bitcoin. This time round, he expects the digital asset to
Cryptocurrency networks are secured by advanced mathematics, but criminal networks in France are bypassing it entirely with iron bars and home invasions. In a terrifying
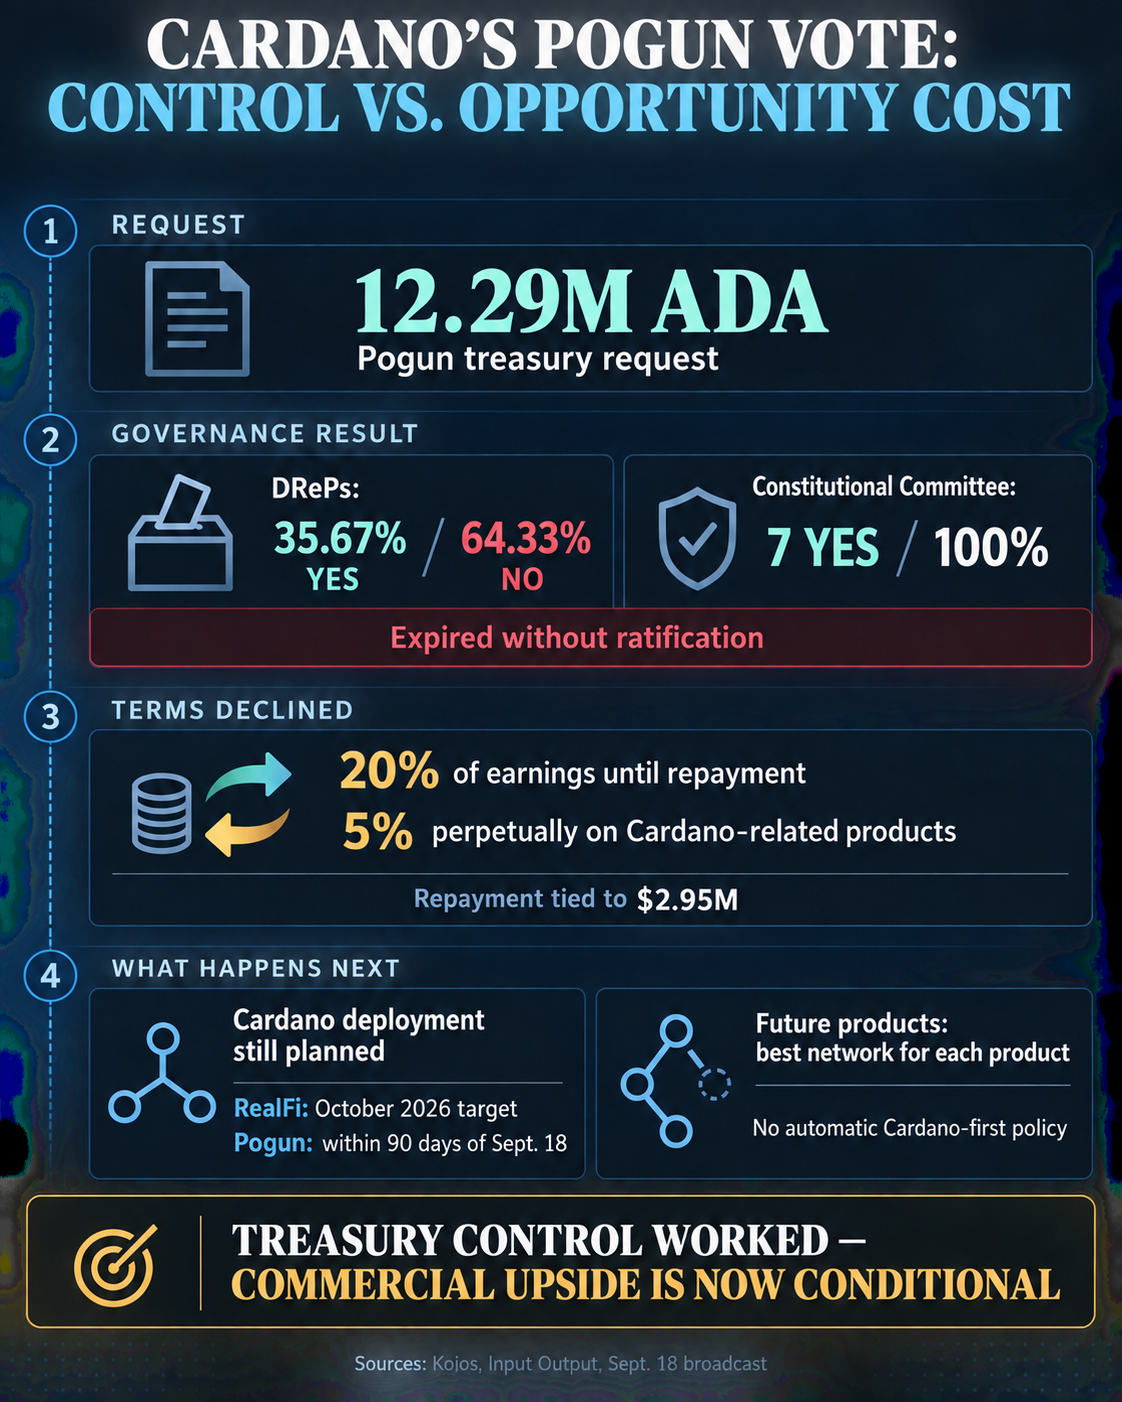
Cardano’s delegated governance voters let a 12.29 million ADA request for Pogun expire without ratification, showing that Input Output’s history as a founding builder does

TL;DR VanEck has taken a closer look at dilution inside Metaplanet’s Bitcoin treasury strategy. Its analysis points to executive option capacity equal to 22.4% of
